Cycle counting should be your warehouse's primary inventory control, not a side task squeezed in when volume slows down. Count a rotating subset of SKUs continuously, count blind, investigate every meaningful variance, and reserve full physical inventory for audits or ERP go-lives.
TL;DR:
- Cycle counting should be the main method of inventory control, focusing on rotating subsets of SKUs to prevent accuracy decay between annual counts.
- The most effective cycle count method combines ABC-weighted, location-based, and control group techniques tailored to inventory value, risk, and process issues.
- Automated systems, barcode scanning, and real-time variance alerts significantly reduce errors and speed up investigation processes.
- A healthy program maintains over 95% inventory record accuracy, with world-class operations aiming for 98% or higher, and escalates issues if below 95% for two consecutive periods.
- Leadership support, clear roles, documented SOPs, and ongoing variance analysis are critical to sustaining accurate cycle counting and process improvement efforts.
Table of Contents
- What Cycle Counting Best Practices Look Like Compared to Physical Inventory
- Cycle Counting Methods: ABC, Random, Location-Based, and Control Groups
- Building a Cycle Count Process Operations Teams Can Standardize
- Best Practices for People, Process, and Place Controls
- Technology That Cuts Cycle Count Errors and Speeds Investigations
- Measuring Cycle Count Success: The KPIs That Matter
- Common Cycle Counting Mistakes and Quick Fixes
- Running a Control-Group Pilot Before You Scale
- Why Cycle Counting Is an Operations Leader's Real Lever
- How TKD Consulting Builds a Cycle Counting Program That Sticks
- Sources
- FAQ
What Cycle Counting Best Practices Look Like Compared to Physical Inventory
Cycle counting is a perpetual auditing method: you count a small, rotating subset of items on a regular schedule instead of shutting down operations once a year to count everything at once, as Wikipedia's overview of the practice lays out. The math is simple. If your warehouse holds 10,000 SKUs and you count 100 a day, you touch the entire catalog roughly every 100 working days, and your fastest-moving items far more often than that.
The operational case for cycle counting over annual-only counts comes down to timing and managing critical spare parts effectively, as highlighted in Refurbished Starters for Fleet maintenance. When you find a variance three days after it happened, the receiving clerk who mis-scanned a pallet is still on shift and remembers the load. When you find it eleven months later during a year-end count, that trail is cold and the discrepancy just becomes a write-off. Fabrico's comparison of cycle counting versus physical inventory makes the case that continuous counting prevents the accuracy decay you see between annual events, because errors get caught and corrected while the cause is still traceable.
That doesn't mean physical counts disappear entirely. You still need a full count in a few specific situations:
- Year-end financial audits where auditors require a complete, dated inventory valuation
- ERP or WMS go-lives, where you need a clean opening balance before the new system starts tracking transactions
- Data cleanup after a merger, a warehouse consolidation, or a known systemic error that cycle counting alone can't isolate fast enough
Outside those events, a warehouse running disciplined cycle counts rarely needs to stop the floor to count anything.
Cycle Counting Methods: ABC, Random, Location-Based, and Control Groups
Most programs fail not because nobody counts, but because everything gets counted the same way regardless of value or risk. Matching the method to the item is what separates a mature program from a checklist nobody trusts.
-
ABC/Pareto-weighted counting. This is the backbone of most inventory cycle counting programs. You rank items by value or usage, then count the top tier far more often than the bottom. A items, typically a minority of SKUs that represent the bulk of inventory value, get counted monthly to quarterly. B items get a quarterly cadence, and C items are counted once or twice a year, according to Storekeeper's breakdown of cycle counting methods. The logic: a $2 miscount on a slow-moving bolt matters far less than a $4,000 miscount on the part that ships every day.
-
Random sampling. Instead of tying frequency to value, you pull a statistically representative sample across the whole catalog on a rolling basis. This catches problems ABC counting can miss, like a low-value item that quietly walked off in bulk. It works best as a supplement to ABC, not a replacement, because pure randomness gives your highest-value SKUs no guaranteed protection.
-
Location-based counting. Here you count every SKU in a physical zone, aisle, or bin range in one pass, regardless of ABC class. This is the fastest way to catch misplacements: items scanned into the wrong bin, overflow stock that never made it into the primary location, or a putaway error nobody flagged. Run this quarterly in high-turnover zones and after any layout change.
-
Control-group counting. You pick a small, fixed set of SKUs and count them repeatedly, sometimes weekly, over several weeks. Because the same items get checked again and again, any process defect (a bad label, a UoM mismatch, a receiving error) shows up fast and repeatedly instead of getting buried in a once-a-quarter rotation. ProjectManager's guide to cycle counting recommends control groups specifically as a launch tactic, before scaling to a full ABC rotation, because they expose systemic issues while the stakes are still low.
-
Hybrid designs. Most mature operations blend two or three of these. A common pattern: ABC counting drives the baseline schedule, location-based sweeps run quarterly in the highest-traffic zones, and a rotating control group of 20 to 50 SKUs runs continuously to catch process drift between the bigger rotations.
Pick the mix based on what's actually failing. If shrinkage complaints cluster around a specific aisle, run location-based counts there before you touch the ABC schedule.
Building a Cycle Count Process Operations Teams Can Standardize
A cycle count process that isn't written down as an SOP will drift the moment the person who "just knows how to do it" goes on vacation. The sequence below, grounded in the widely used step-by-step model from Stockount's cycle count process guide and the formal count procedures documented in Oracle's cycle count workflow, is what you standardize.
Selection. Your WMS or ERP pulls the day's count list based on your ABC schedule, a random sample, or a location sweep. Set a realistic daily volume: for most mid-market warehouses, that's somewhere between 20 and 100 SKUs a day, sized so counters can finish without rushing the recount step.
Freeze and snapshot. Before anyone touches a bin, freeze transactions on those SKUs and take an ERP or WMS snapshot of the system quantity. This timestamp is what every later variance gets measured against. If receiving or picking touches a frozen SKU before the count closes, the count is invalid and needs to restart.
Blind count. Counters should never see the system quantity before they count. This is the single discipline that matters most in the entire process, because showing a counter the expected number invites confirmation bias, where they see what they expect to see rather than what's actually on the shelf. Pair counters on high-value A items when staffing allows.
Recount on threshold. Not every variance needs a second look, but material ones do.
Investigate before adjusting. Before anyone touches the inventory record, check for open receipts not yet posted, open pick tickets, overflow bins outside the primary location, and unit-of-measure mismatches (a case counted as an each, for instance). Most "shrinkage" turns out to be a transaction timing issue or a UoM error, not a real loss.
Adjust with a reason code, and log everything. Every adjustment needs a documented reason code, an approver, and a full audit trail: counter ID, recount ID (if one happened), before and after quantities, timestamps, and the approver's name. This is what makes a variance defensible to an auditor and useful to whoever runs next month's root-cause review.
- Selection: pull the day's list from ABC schedule, random sample, or location sweep
- Freeze: lock transactions, snapshot system quantity, timestamp it
- Blind count: no visibility into system quantity while counting
- Recount: apply class-based thresholds, use an independent second counter
- Investigate: check receipts, picks, overflow bins, UoM before adjusting
- Adjust: log reason code, approver, and full audit trail
Pro Tip: Build your recount threshold table into the count sheet itself, not a separate policy document. A counter who has to look up the rule mid-count will skip it under time pressure.
Best Practices for People, Process, and Place Controls
The mechanics above only work if the people running them are trained, accountable, and working in a warehouse that isn't fighting them at every turn. Cycle count accuracy is as much a people and housekeeping problem as a math problem.
Start with named roles. Someone owns counting, someone independent owns investigation, and someone with authority (usually a supervisor or inventory control manager) owns approval. Never let the same person count, investigate, and approve their own adjustment. That single-person shortcut is how bad numbers get baked into the system quietly.
Train counters on the actual SOP, not just "go count aisle 12." That includes scanner use, UoM conventions, and what to do when a bin looks wrong before they even start counting. Before you scale a program, get basic 6S discipline in place: segregate scrap and expired stock so it doesn't get counted as sellable inventory, label every location clearly, and keep bins visually clean enough that a miscount is obvious rather than buried under clutter.
Set tolerance thresholds by ABC class, escalate consistently, and hold a standing cadence: daily variance review for anything over threshold, and a monthly meeting where you look at reason-code trends across the whole warehouse, not just individual variances. Storekeeper's cycle counting insights note that reason codes only pay off when someone actually uses them to prioritize fixes upstream, not just file them.
- Assign named counter, investigator, and approver roles with no overlap
- Run 6S basics (segregate, label, clean) before scaling any count program
- Train and test every counter on blind-count discipline and UoM rules
- Set ABC-based tolerance and escalation thresholds in writing
- Hold daily variance stand-ups and a monthly root-cause review
- Track reason codes as a prioritization tool, not just a filing requirement
| Control area | What good looks like | Common failure |
|---|---|---|
| Roles | Counter, investigator, approver are three different people | One person counts and self-approves |
| Training | Counters tested on blind-count and UoM rules before going live | Counters trained verbally, no documentation |
| Thresholds | Written tolerance table by ABC class | Ad hoc judgment calls per supervisor |
| Cadence | Daily variance review, monthly root-cause meeting | Variances reviewed only during audit prep |
Technology That Cuts Cycle Count Errors and Speeds Investigations
Paper count sheets and manual keying at end of shift are where most transcription errors get introduced, and they're also the easiest thing in the whole program to fix. Scan-to-system mobile apps let a counter scan a barcode, enter a quantity, and post it directly into the WMS or ERP in real time, which eliminates the batch-entry step where numbers get mistyped or transposed, as Wikipedia's cycle count entry notes.
Integration with your ERP or WMS matters more than the scanning hardware itself. A system that auto-generates count sheets from your ABC schedule, applies the freeze automatically, and timestamps the snapshot removes several manual steps where human error creeps in.
Real-time variance alerts are the other piece worth prioritizing. If a count comes in outside threshold, the system should flag it and route it to a recount queue immediately, while the counter is still standing at the bin, rather than surfacing the problem in a report three days later when the context is gone.
- Prioritize scan-to-system posting over paper sheets and end-of-shift manual entry
- Confirm your WMS/ERP can auto-generate count sheets from your ABC schedule
- Set variance alerts to trigger a recount queue in real time, not in a batch report
- Weigh barcode scanning against RFID: barcode is cheaper and sufficient for most mid-market operations, while RFID earns its cost mainly in high-SKU-density or high-shrink environments
Barcode scanning covers the vast majority of mid-market use cases. RFID makes financial sense mainly where SKU density is extreme or shrink is a documented, chronic problem, since the tag and infrastructure cost only pays back at volume.
Measuring Cycle Count Success: The KPIs That Matter
Inventory record accuracy (IRA) is the metric everything else rolls up to. Calculate it as the number of SKUs counted with zero variance divided by total SKUs counted, times 100. If you count 200 SKUs in a week and 190 match the system exactly, that's a 95% IRA for the week.
Healthy programs run above 95% IRA; world-class operations hold 98% or higher. Anything drifting below 95% for two consecutive reporting periods should trigger an escalation review, not just a note in a meeting deck.
Beyond IRA, track count completion rate (scheduled counts actually completed on time) and variance trend by reason code, location, and ABC class. A rising trend of "receiving error" reason codes pointing at one dock door tells you exactly where to send a process fix, which matters more for inventory turns and working capital than the raw accuracy number alone. Watch for concentration, too: if 80% of your dollar variance comes from 5% of your SKUs, that's not a counting frequency problem, it's a process problem sitting in one part of the warehouse.
Common Cycle Counting Mistakes and Quick Fixes
Most accuracy problems trace back to a handful of repeat offenders. Snapshot timing errors happen when receiving or picking touches a SKU after the freeze, corrupting the count before it starts; fix it by locking transactions at the system level, not just asking people nicely to hold off.
UoM mismatches and duplicate SKU numbers cause phantom variances that have nothing to do with real inventory loss; catch these at the source by auditing your item master quarterly, not just during counts.
Skipping blind counts, or approving adjustments without investigating first, are the two habits that quietly destroy trust in the whole program. Once a counter learns the system number in advance, every future count from that person is compromised.
- Lock transactions at the system level during freeze, don't rely on verbal holds
- Audit the item master for UoM and duplicate-SKU errors quarterly
- Never approve an adjustment before the investigation checklist is complete
- Review reason-code trends monthly and route repeat causes to the department that owns them
Running a Control-Group Pilot Before You Scale
Don't launch a full ABC rotation on day one. Pick 20 to 50 representative SKUs spread across your A, B, and C classes, and count that same group repeatedly for two to four weeks. Log every discrepancy with a reason code and watch the variance rate over successive counts, not just the count-to-count number itself.
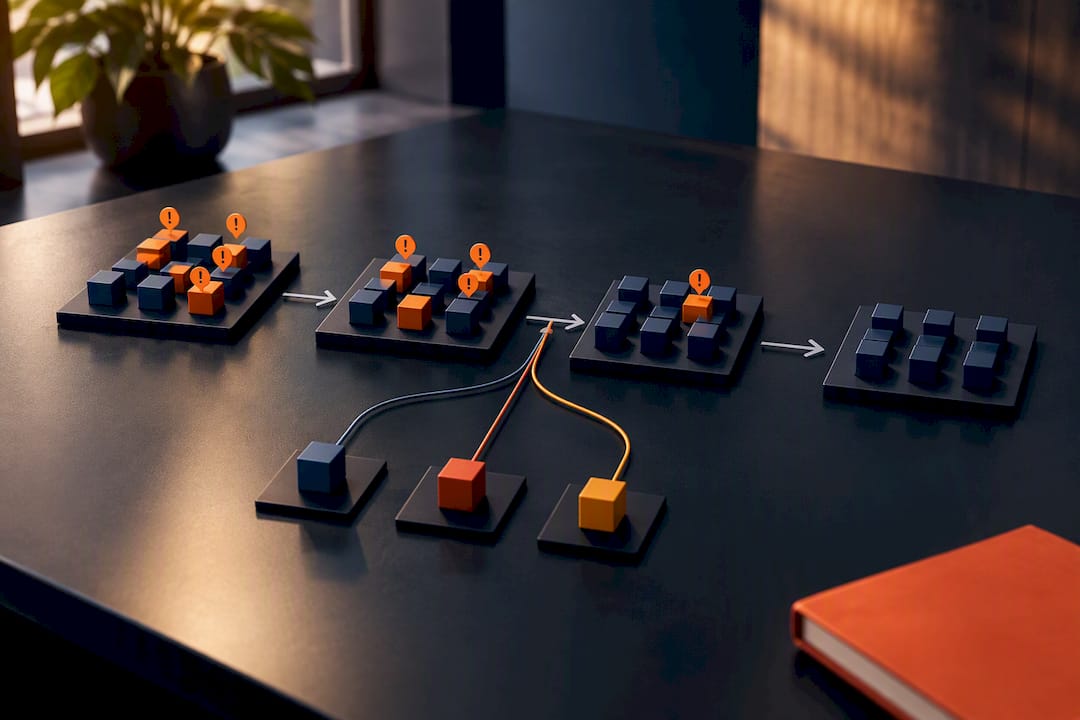
You're looking for variance decay: if the same group's error rate drops meaningfully across three or four repeated counts, your counters and process are working. If it doesn't decay, or one cause (say, a specific receiving dock) keeps reappearing, fix that upstream process before you add more SKUs to the schedule.
Scale to the full ABC rotation once you see a reproducible decline in variance, a stable and explainable mix of reason codes, and counters who no longer need close supervision. In field engagements, pilots run with structured coaching and a fixed weekly review cadence have produced cycle-time reductions in the 25 to 40% range once the process stabilized.
Pro Tip: If your control group shows the same reason code three weeks running, stop increasing count frequency and go fix the upstream cause instead. More counting won't fix a receiving problem.
Why Cycle Counting Is an Operations Leader's Real Lever
Cycle counting is the feedback loop that keeps a warehouse from finding out about a stockout at the worst possible moment, or discovering six months of obsolete inventory sitting in an overflow bin nobody logged. The accuracy number gets attention, but the real value is upstream: every reason code is a pointer to a broken process somewhere in receiving, picking, or putaway.
What determines whether a program survives past the pilot is leadership support, not the counting method chosen. A 60-day pilot with a defined scorecard, a fixed meeting cadence, and someone accountable for reviewing reason codes each month will outlast a technically superior counting method with no governance behind it. The count sheet is the easy part. The discipline to act on what it tells you is where most programs actually fail.
— David
How TKD Consulting Builds a Cycle Counting Program That Sticks
Most warehouses don't fail at cycle counting because they picked the wrong ABC frequency. They fail because nobody owns the follow-through: the reason-code review, the escalation meeting, the SOP update after a control-group pilot exposes a receiving problem. TKD Consulting's 90-Day Operations Audit is built specifically for that gap. It maps your current counting process, roles, and variance handling against what your ERP and floor team can actually sustain, then hands you a prioritized 60-day action plan with the scorecards and meeting cadences built in, not just a slide deck describing what's broken.
If you're still deciding whether to run the pilot internally or bring in outside eyes, the honest answer is: run a small control group yourself first, then call in help if the variance won't decay or leadership can't hold the cadence. TKD Consulting also runs a paid discovery call for $500 if you want a second opinion before committing to a full audit. For teams that already know they need hands-on implementation support, the Operations Audit page has the scope and next steps.
Sources
- How to Do a Cycle Count in a Warehouse: Step-by-Step Process for Operations Teams
- Cycle Counting: What It Is, Methods and How Often to Count | Storekeeper Blog
- Cycle count procedures — Oracle documentation
- Cycle counting — ProjectManager blog
FAQ
What Is the 80/20 Rule for Cycle Counting?
A items typically get counted monthly to quarterly, while B and C items are counted quarterly or just once or twice a year.
What Are Some Effective Cycle Counting Techniques?
The most effective techniques combine ABC-weighted counting for value-based frequency with location-based sweeps for catching misplacements, and a rotating control group for exposing process defects. The standard step-by-step process, freeze, blind count, recount on threshold, investigate, then adjust with a reason code, is what makes any of these techniques reliable rather than just busy work.
How Often Should Cycle Counts Be Done?
Frequency depends on ABC class: A items monthly to quarterly, B items quarterly, and C items once or twice a year, adjusted for usage volatility. A control-group pilot typically runs weekly for two to four weeks before you commit to a full rotation schedule.
What Does TKD Consulting Charge to Help Design a Cycle Counting Program?
TKD Consulting's 90-Day Operations Audit is a fixed one-off engagement, and current pricing for that and related services like Operations Consulting is listed on the TKD Consulting site. A $500 paid discovery call is available for teams that want a scoped conversation before committing to a full audit.
How Is Cycle Counting Different From Physical Inventory?
Cycle counting checks a rotating subset of SKUs continuously so operations never fully stop, while physical inventory counts everything at once, usually annually, and typically halts picking and shipping for the duration. Most mature programs use cycle counting as the primary control and keep physical counts as a backstop for audits or system go-lives.