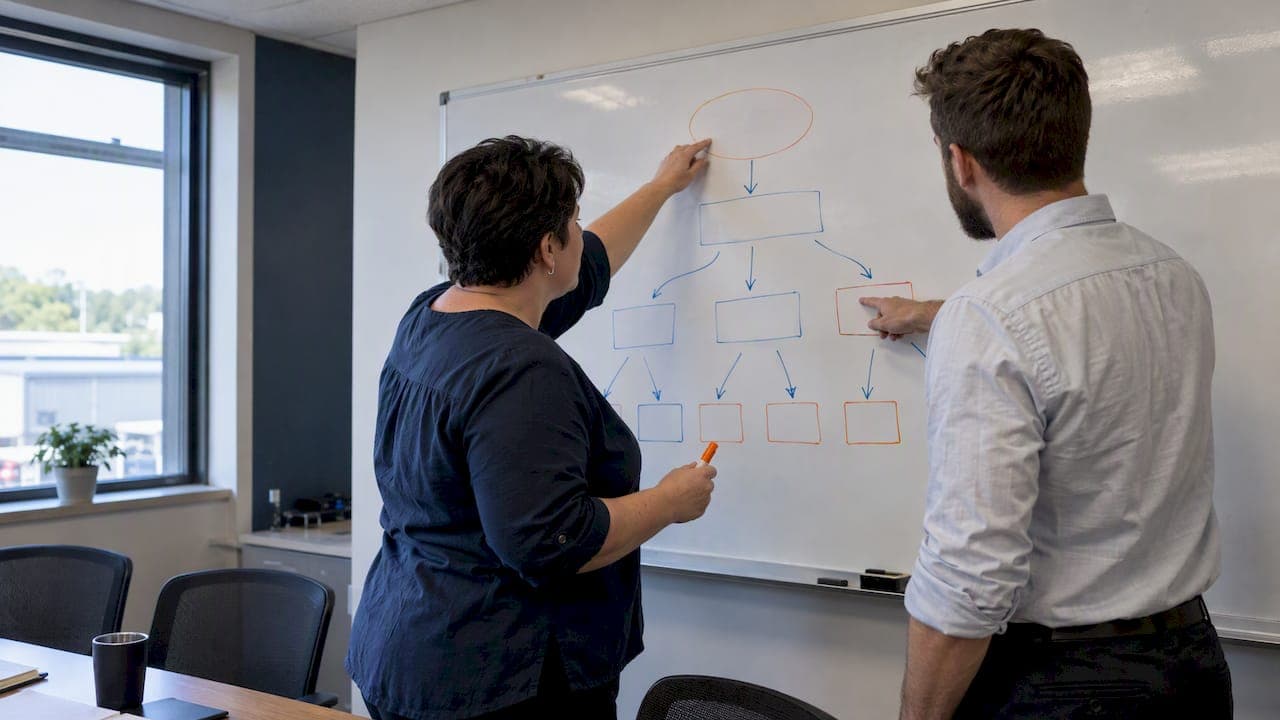
Cascading KPIs map three to five strategic outcomes to the signals and measurable metrics that actually drive them, connecting executive intent to the decisions a frontline team makes every day. The payoff is alignment you can see on a scorecard, not just in a strategy deck. Start by picking those outcomes and assigning one or two driver metrics per function before you add anything else.
TL;DR:
- A strong cascade typically includes three to five strategic outcomes, each linked to one or two driver metrics owned by specific managers.
- Frontline metrics should be tied to decision-making actions and reviewed weekly or monthly, with targets set to trigger clear responses.
- KPI definitions must be documented, owned, and governed consistently to prevent discrepancies and stale data issues.
- Avoid measuring every possible metric; instead, focus on those that directly inform decisions and reveal early warning signals.
- Running a short 60 to 90-day pilot with a designated owner helps validate the cascade’s effectiveness before broad implementation.
Table of Contents
- Why cascading KPIs matter for strategy execution
- How do you build a cascade from strategy to the frontline?
- A KPI tree example and how many metrics to keep at each level
- Governance and metric definitions: keeping KPIs trusted
- Common pitfalls and practical fixes
- A 60 to 90-day pilot checklist to prove the cascade works
- What actually works when you run this in practice
- Building your cascade with TKD's Operations Audit
- FAQ
- Sources
Why cascading KPIs matter for strategy execution
A cascade only earns its place when leaders treat it as an operating system, not a slide from the annual planning offsite — see our guide on the role of KPIs in customer experience for how these metrics tie into operational scorecards. Done well, it turns strategy into something a department head or shift supervisor can act on this week, because every metric on their dashboard traces back to a company-level outcome.
McKinsey research on organizational alignment found that companies connecting purpose, strategy, goals, and operational planning are associated with a higher likelihood of earnings margins above the median. That is an association, not proof that alignment causes the margin, but it matches what shows up on the floor: teams that understand how their numbers feed the company's numbers tend to make faster, better-aligned calls.
Balanced Scorecard practice backs this up from a different angle. The original logic behind the scorecard is that outcome measures (lagging) only become useful when they are causally linked to driver measures (leading) that teams can actually influence day to day, a point reinforced by research on causal links in the Balanced Scorecard.
A cascade built on that logic gives you three things at once:
- A shared language between the boardroom and the floor, so "grow margin" turns into a number a plant manager owns.
- Early warning signals, because lead indicators move before the lagging outcome does.
- A way to test whether your strategy theory actually holds, since you can trace a missed target back to the driver that moved.
One figure worth building the case around: organizations with strong strategic alignment are more likely to post above-median earnings margins, underscoring why a cascade is worth the setup effort.
How do you build a cascade from strategy to the frontline?
A cascade works in four stages, moving from the executive floor to the production floor in a predictable sequence.
- Clarify three to five strategic outcomes and their success signals. Use the Goals→Signals→Metrics method from the LinkedIn DPH framework: name the goal, decide what evidence would show it is happening, then choose a measurable proxy for that evidence.
- Map the drivers behind each outcome and assign one or two departmental KPIs per driver, with a named owner. If the outcome is margin expansion, drivers might be scrap rate and labor efficiency, each owned by a specific manager.
- Define frontline metrics and daily or weekly signals tied to a decision. A frontline number only belongs on the cascade if someone changes behavior when it moves.
- Set targets, decision rules, and a short review cadence, typically weekly for operations, monthly for cross-functional review, and quarterly for strategic recalibration.
Resist the urge to measure everything you can. Every added metric is another thing someone has to maintain and trust, and a cascade that tries to capture every nuance of the business usually collapses under its own weight within two quarters.
Pro Tip: When you can't measure the real driver directly, pick the closest available proxy and say so explicitly, rather than inventing a composite metric nobody can audit.
A KPI tree example and how many metrics to keep at each level
A KPI tree is the visual version of the cascade: strategic outcomes at the top, departmental drivers in the middle, frontline signals at the bottom, each level narrower in scope and higher in frequency than the one above it.

The LinkedIn DPH framework offers illustrative design ranges that work as a starting template rather than a fixed rule. Typically, this might mean a few strategic KPIs, around a dozen departmental KPIs across functions, and twenty or more frontline metrics, though smaller teams may need fewer departmental KPIs.
A few practical rules keep the tree from sprawling:
- Pick the signal before you pick the metric. Decide what evidence of progress looks like, then find a number that approximates it, because no single metric captures a goal perfectly.
- Expand a level only when a decision-maker is missing information they need, not because a number is interesting.
- Trim a level when two metrics move together consistently. One of them is redundant.
Governance and metric definitions: keeping KPIs trusted
A cascade falls apart quietly when two teams calculate the "same" KPI differently and nobody notices until a leadership review turns into an argument about whose number is right. MIT Sloan's guidance on KPI governance treats this as a leadership function, not a data-team chore.
Every metric in the dictionary needs:
- A formula written down in plain language, not just a dashboard label.
- A named owner accountable for accuracy, not just visibility.
- The source system it pulls from and how often it refreshes.
- Target logic: how the number was set, and what "red" actually triggers.
- Documented exclusions, so nobody debates edge cases mid-meeting.
Beyond the dictionary, build a lightweight governance routine: a review board that meets monthly, a change log when a definition shifts, and periodic checks that the underlying data is still clean. The same MIT Sloan research notes that AI can sharpen these systems into "smart KPIs" with better predictive power, but it strengthens governance rather than substituting for it; a model is only as trustworthy as the metric definition feeding it.
Pro Tip: Before adding a new KPI, write its one-sentence decision trigger first. If you can't state what action a red result would cause, the metric isn't ready for the dictionary.
For a deeper look at building the reporting layer around these definitions, see our guide to operational dashboards.
Common pitfalls and practical fixes
Most cascades fail for the same handful of reasons, and most of those reasons are fixable without a full redesign.
- Metric proliferation: dashboards grow past what anyone checks regularly. Fix by cutting to the metrics that actually trigger a decision.
- Inconsistent definitions: two teams report different numbers under the same label. Fix by publishing and enforcing a single metric dictionary.
- Missing causal links: lag indicators exist with no lead indicator feeding them. Fix by mapping each outcome to at least one driver metric before reporting it.
- Stale data: numbers get reviewed weeks after the decision window closes. Fix by automating simple reports rather than compiling them by hand.
- Unclear ownership: a metric moves and nobody is responsible for responding. Fix by naming an owner and a service-level agreement for each KPI.
If more than two or three of these show up at once, pause and redesign the cascade rather than patching it metric by metric.
A 60 to 90-day pilot checklist to prove the cascade works
A pilot proves the model before you roll it out company-wide, and the FHWA's guidance on operational reporting makes the case directly: even a report built around one or two measures can broaden the conversation and build the case for expanding it.
- Pick one business unit or function and limit the pilot to three to five KPIs.
- Name an owner for each metric and confirm the data feed actually works before launch.
- Set the review cadence: weekly for frontline signals, monthly for the pilot owner's review.
- Build the minimum scorecard and the metric dictionary entries alongside it.
- Draft a 60-day prioritized action list tied to what the early data shows.
- Review results against the original decision triggers, not just whether the number moved, before deciding to scale.
What actually works when you run this in practice
Most cascade failures I see are not analytical, they are organizational: nobody owns the handoff from the diagnostic phase to the daily grind of running the scorecard. A pilot with a short runway and a named owner beats a company-wide rollout launched all at once, because it forces the definitions and cadence to prove themselves before you scale them.
The discipline that matters most is the one least discussed: writing a 60-day action list specific enough that a floor manager can start executing it on Monday morning, not file it as another strategy document.
— David
Building your cascade with TKD's Operations Audit
We built the 90-Day Operations Audit around exactly this problem: turning a strategy conversation into a working scorecard a team actually uses. The engagement maps your people, processes, and performance systems against your stated goals, then hands you a prioritized 60-day action plan instead of a deck.
This services best suits owner-operators and mid-market operations leaders who need senior operational judgment without adding another full-time executive.
- A structured diagnostic of current metrics, ownership, and data feeds.
- A working scorecard and metric dictionary, not just recommendations.
- Coaching on the meeting cadence that keeps the cascade alive after we leave.
If you want a second set of eyes on your own cascade, visit the Operations Audit page or start with a discovery call.
FAQ
What is a cascading KPI?
A cascading KPI is a metric that connects a company-level strategic outcome down through departmental drivers to the daily signals a frontline team tracks. The structure follows a goal-to-signal-to-metric logic, so each number at every level ties back to a business outcome leadership actually cares about.
What are the four types of KPIs?
KPIs are commonly grouped as strategic (board-level outcomes), operational (departmental drivers), leading (predictive signals that move before results do), and lagging (outcome measures that confirm results after the fact). A well-built cascade uses a mix of leading and lagging indicators with causal links between them so teams get warning signs, not just scorecards.
What are the three types of KPIs?
A simpler framing groups KPIs as strategic, operational, and tactical, moving from company-wide outcomes down to the daily measures a frontline team watches. This mirrors the strategic, departmental, and frontline levels used in a typical KPI tree.
What are the five key performance indicators?
There is no single universal list of five KPIs that applies to every business, since the right metrics depend on your specific strategic outcomes and drivers. A cascade built with the Goals, Signals, and Metrics framework typically starts with four to five strategic KPIs and expands from there into departmental and frontline layers.
How many KPIs should a department track?
A department generally works best with two or three driver KPIs tied to a specific strategic outcome, supported by a broader set of frontline signals reviewed daily or weekly. Illustrative design ranges suggest eight to twelve departmental KPIs total across a function, with more granular signals below that.
Sources
- Goals, Signals, and Metrics | The LinkedIn DPH Framework
- Governance for smarter KPIs
- The aligned organization